# Render PDF documents as HTML and image files
Convert PDF files to HTML, PNG, or JPEG using the GroupDocs.Viewer Python API. Learn basic rendering techniques.
[GroupDocs.Viewer for Python](https://products.groupdocs.com/viewer/python-net) allows you to render your PDF files in HTML, PNG, and JPEG formats. Use this library to implement a simple PDF viewer within your Python application (web or desktop).
Create a [Viewer](#) class instance to get started with the GroupDocs.Viewer API. Pass a document you want to view to the class constructor. You can load the document from a file or stream. Call one of the [Viewer.view](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer/viewer/#methods) method overloads to convert the document to HTML or image format. These methods allow you to render the entire document or specific pages.
{{< button style="primary" link="https://products.groupdocs.app/viewer/pdf" >}} {{< icon "gdoc_person" >}} View PDF files online {{< /button >}} {{< button style="primary" link="https://github.com/groupdocs-viewer/GroupDocs.Viewer-for-Python-via-.NET" >}} {{< icon "gdoc_github" >}} View demos and examples on GitHub {{< /button >}}
## Supported Page Layout file formats
GroupDocs.Viewer supports the following PDF and Page Layout file formats:
* [Portable Document Format](https://docs.fileformat.com/pdf/) (.PDF)
* [Microsoft XML Paper Specification](https://docs.fileformat.com/page-description-language/xps/) (.XPS)
* [Open XML Paper Specification](https://docs.fileformat.com/page-description-language/oxps/) (.OXPS)
* [LaTeX Source Document](https://docs.fileformat.com/page-description-language/tex/) (.TEX)
## Render PDF files as HTML
Create an [HtmlViewOptions](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/htmlviewoptions/) class instance and pass it to the [Viewer.view](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer/viewer/#methods) method to convert a PDF file to HTML. The `HtmlViewOptions` class properties allow you to control the conversion process. For instance, you can embed all external resources in the generated HTML file, minify the output file, and optimize it for printing. Refer to the following documentation section for details: [Rendering to HTML]({{< ref "viewer/python-net/developer-guide/rendering-documents/rendering-to-html/_index.md" >}}).
### Create an HTML file with embedded resources
To save all elements of an HTML page (including text, graphics, and stylesheets) into a single file, call the [HtmlViewOptions.for_embedded_resources](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/htmlviewoptions/#methods) method and specify the output file name.
{{< tabs "example1">}}
{{< tab "Python" >}}
```python
from groupdocs.viewer import Viewer
from groupdocs.viewer.options import HtmlViewOptions
def render_pdf_to_html():
# Load PDF document
with Viewer("sample.pdf") as viewer:
# Create an HTML files.
# {0} is replaced with the current page number in the file name.
viewOptions = HtmlViewOptions.for_embedded_resources("render_pdf_to_html/pdf_page_{0}.html")
viewer.view(viewOptions)
if __name__ == "__main__":
render_pdf_to_html()
```
{{< /tab >}}
{{< tab "sample.pdf" >}}
{{< tab-text >}}
`sample.pdf` is the sample file used in this example. Click [here](https://docs.groupdocs.com/viewer/python-net/_sample_files/rendering-basics/render-pdf-documents/sample.pdf) to download it.
{{< /tab-text >}}
{{< /tab >}}
{{< tab "render-pdf-to-html-outputs.zip" >}}
```text
render_pdf_to_html/pdf_page_1.html (832 KB)
render_pdf_to_html/pdf_page_2.html (80 KB)
```
[Download full output](https://docs.groupdocs.com/viewer/python-net/_output_files/rendering-basics/render-pdf-documents/render_pdf_to_html/render-pdf-to-html-outputs.zip)
{{< /tab >}}
{{< /tabs >}}
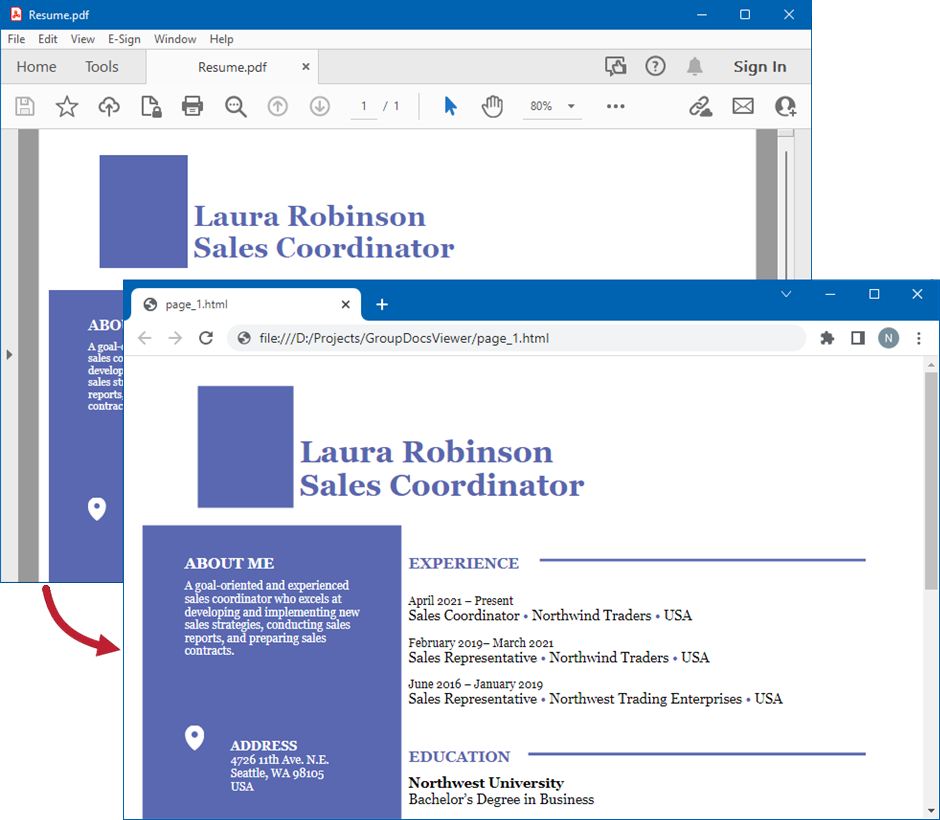
The following image demonstrates the result:
### Create an HTML file with external resources
If you want to store an HTML file and additional resource files (such as fonts, images, and stylesheets) separately, call the [HtmlViewOptions.for_external_resources](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/htmlviewoptions/#methods) method and pass the following parameters:
* The output file path format
* The path format for the folder with external resources
* The resource URL format
{{< tabs "example2">}}
{{< tab "Python" >}}
```python
from groupdocs.viewer import Viewer
from groupdocs.viewer.options import HtmlViewOptions
def render_pdf_to_html_external():
# Load PDF document
with Viewer("sample.pdf") as viewer:
# Create an HTML file for each PDF page.
# Specify the HTML file names and location of external resources.
# {0} and {1} are replaced with the current page number and resource name, respectively.
viewOptions = HtmlViewOptions.for_external_resources("render_pdf_to_html_external/pdf_page_{0}.html", "render_pdf_to_html_external/pdf_page_{0}/resource_{0}_{1}", "render_pdf_to_html_external/pdf_page_{0}/resource_{0}_{1}")
viewer.view(viewOptions)
if __name__ == "__main__":
render_pdf_to_html_external()
```
{{< /tab >}}
{{< tab "sample.pdf" >}}
{{< tab-text >}}
`sample.pdf` is the sample file used in this example. Click [here](https://docs.groupdocs.com/viewer/python-net/_sample_files/rendering-basics/render-pdf-documents/sample.pdf) to download it.
{{< /tab-text >}}
{{< /tab >}}
{{< tab "render-pdf-to-html-external-outputs.zip" >}}
```text
render_pdf_to_html_external/pdf_page_1.html (8 KB)
render_pdf_to_html_external/pdf_page_1/resource_1_f.woff (5 KB)
render_pdf_to_html_external/pdf_page_1/resource_1_f1.woff (7 KB)
render_pdf_to_html_external/pdf_page_1/resource_1_f2.woff (9 KB)
render_pdf_to_html_external/pdf_page_1/resource_1_f3.woff (10 KB)
render_pdf_to_html_external/pdf_page_1/resource_1_f4.woff (7 KB)
render_pdf_to_html_external/pdf_page_1/resource_1_f5.woff (3 KB)
render_pdf_to_html_external/pdf_page_1/resource_1_f6.woff (1 KB)
render_pdf_to_html_external/pdf_page_1/resource_1_i.png (570 KB)
render_pdf_to_html_external/pdf_page_1/resource_1_i1.png (109 bytes)
[TRUNCATED] (17 files total)
```
[Download full output](https://docs.groupdocs.com/viewer/python-net/_output_files/rendering-basics/render-pdf-documents/render_pdf_to_html_external/render-pdf-to-html-external-outputs.zip)
{{< /tab >}}
{{< /tabs >}}
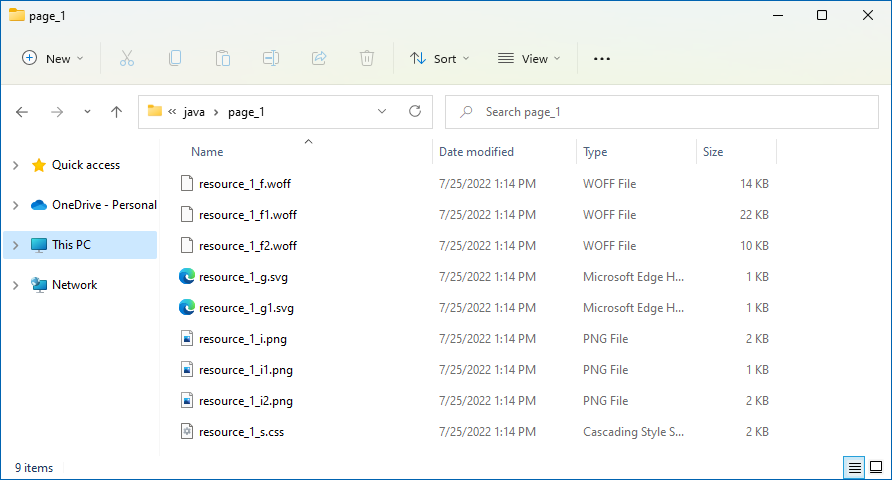
The image below demonstrates the result. External resources are placed in a separate folder.
### Create HTML with fixed layout
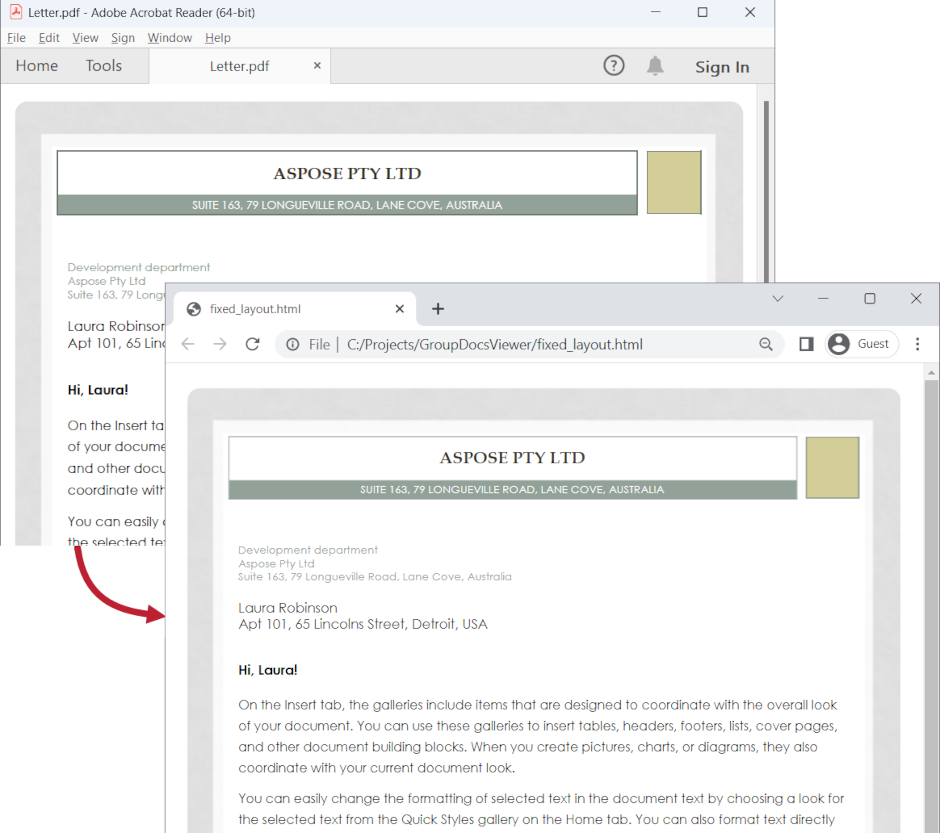
By default, PDF and EPUB documents are rendered to HTML with fixed layout to ensure that the output HTML looks the same as a source document. Rendering to fixed layout means that all the HTML elements are absolutely positioned to the container element. And container element has a fixed size so browser window resizing will not have an effect on the position and size of elements in a document.
The following image demonstrates PDF document rendered HTML with fixed layout:
### Adjust image quality in the output HTML file
The [HtmlviewOptions.pdf_options.image_quality](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/pdfoptions/#properties) methods allows you to specify the quality of images in the output HTML file. You can set this property to one of the following values:
* [ImageQuality.LOW](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/imagequality/#members) --- The image resolution is low (96 DPI), and the image size is small. Use this value to increase the conversion performance.
* [ImageQuality.MEDIUM](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/imagequality/#members) --- The image resolution is medium (192 DPI), and the image size is larger compared to the low quality images.
* [ImageQuality.HIGH](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/imagequality/#members) --- The image resolution is high (300 DPI), and the image size is big. Use of this value may decrease the conversion performance.
The following code snippet shows how to set the medium image quality when rendering a PDF document to HTML:
{{< tabs "example4">}}
{{< tab "Python" >}}
```python
from groupdocs.viewer import Viewer
from groupdocs.viewer.options import HtmlViewOptions, ImageQuality
def render_pdf_with_image_quality():
# Load PDF document
with Viewer("sample.pdf") as viewer:
# Create an HTML files.
# {0} is replaced with the current page number in the file name.
viewOptions = HtmlViewOptions.for_embedded_resources("render_pdf_with_image_quality/pdf_with_image_quality_{0}.html")
# Set image quality to medium.
viewOptions.pdf_options.image_quality = ImageQuality.MEDIUM
viewer.view(viewOptions)
if __name__ == "__main__":
render_pdf_with_image_quality()
```
{{< /tab >}}
{{< tab "sample.pdf" >}}
{{< tab-text >}}
`sample.pdf` is the sample file used in this example. Click [here](https://docs.groupdocs.com/viewer/python-net/_sample_files/rendering-basics/render-pdf-documents/sample.pdf) to download it.
{{< /tab-text >}}
{{< /tab >}}
{{< tab "render-pdf-with-image-quality-outputs.zip" >}}
```text
render_pdf_with_image_quality/pdf_with_image_quality_1.html (5534 KB)
render_pdf_with_image_quality/pdf_with_image_quality_2.html (222 KB)
```
[Download full output](https://docs.groupdocs.com/viewer/python-net/_output_files/rendering-basics/render-pdf-documents/render_pdf_with_image_quality/render-pdf-with-image-quality-outputs.zip)
{{< /tab >}}
{{< /tabs >}}
### Render text as an image
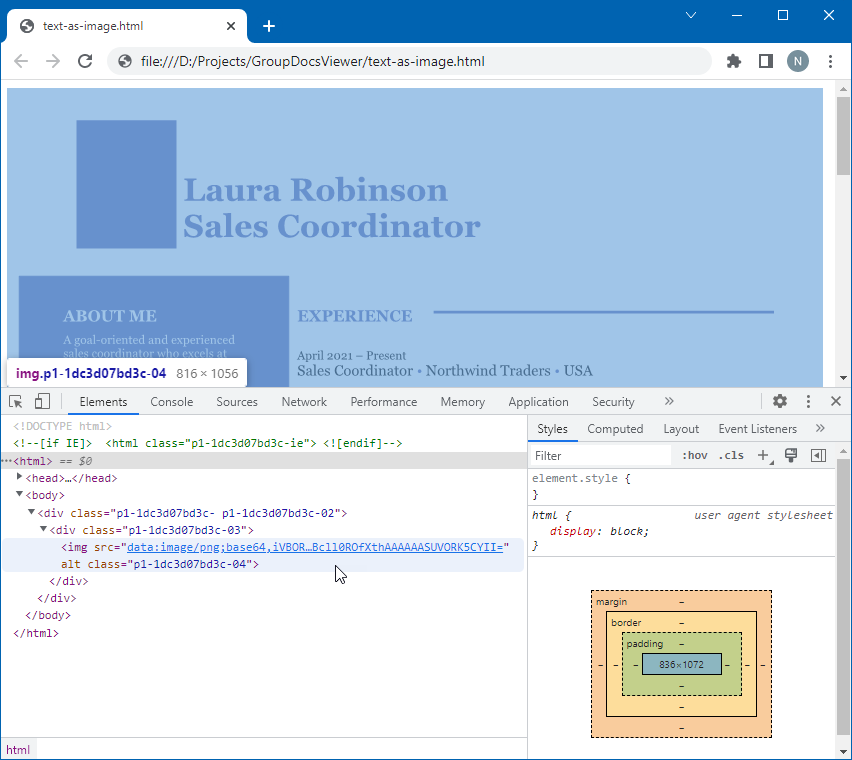
GroupDocs.Viewer supports the [HtmlViewOptions.pdf_options.render_text_as_image](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/pdfoptions/#properties) option that allows you to render text as an image when you convert a PDF file to HTML. In this case, the layout of the output HTML file closely mirrors the layout of the source PDF document.
The following code snippet shows how to enable this option in code:
{{< tabs "example5">}}
{{< tab "Python" >}}
```python
from groupdocs.viewer import Viewer
from groupdocs.viewer.options import HtmlViewOptions, ImageQuality
def render_pdf_text_as_image():
# Load PDF document
with Viewer("sample.pdf") as viewer:
# Create an HTML files.
# {0} is replaced with the current page number in the file name.
viewOptions = HtmlViewOptions.for_embedded_resources("render_pdf_text_as_image/text-as-image_{0}.html")
# Enable rendering text as image.
viewOptions.pdf_options.image_quality = ImageQuality.MEDIUM
viewOptions.pdf_options.render_text_as_image = True
viewer.view(viewOptions)
if __name__ == "__main__":
render_pdf_text_as_image()
```
{{< /tab >}}
{{< tab "sample.pdf" >}}
{{< tab-text >}}
`sample.pdf` is the sample file used in this example. Click [here](https://docs.groupdocs.com/viewer/python-net/_sample_files/rendering-basics/render-pdf-documents/sample.pdf) to download it.
{{< /tab-text >}}
{{< /tab >}}
{{< tab "render-pdf-text-as-image-outputs.zip" >}}
```text
render_pdf_text_as_image/text-as-image_1.html (5463 KB)
render_pdf_text_as_image/text-as-image_2.html (224 KB)
```
[Download full output](https://docs.groupdocs.com/viewer/python-net/_output_files/rendering-basics/render-pdf-documents/render_pdf_text_as_image/render-pdf-text-as-image-outputs.zip)
{{< /tab >}}
{{< /tabs >}}
The image below illustrates the result. PDF content is exported to HTML as an image, so users cannot select or copy document text.
### Enable multi-layer rendering
When you convert a PDF file to HTML, GroupDocs.Viewer creates an HTML document with a single layer (the `z-index` is not specified for document elements). This helps increase performance and reduce the output file size. If you convert a PDF document with multiple layers and want to improve the position of document elements in the output HTML file, use the [HtmlViewOptions.pdf_options.enable_layered_rendering](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/pdfoptions/#properties) method to render text and graphics in the HTML file according to their z-order in the source PDF document.
The following code snippet shows how to enable the multi-layer rendering:
{{< tabs "example6">}}
{{< tab "Python" >}}
```python
from groupdocs.viewer import Viewer
from groupdocs.viewer.options import HtmlViewOptions
def render_pdf_with_layered_rendering():
# Load PDF document
with Viewer("sample.pdf") as viewer:
# Create an HTML files.
# {0} is replaced with the current page number in the file name.
viewOptions = HtmlViewOptions.for_embedded_resources("render_pdf_with_layered_rendering/pdf_with_layered_rendering_{0}.html")
# Enable the multi-layer rendering.
viewOptions.pdf_options.enable_layered_rendering = True
viewer.view(viewOptions)
if __name__ == "__main__":
render_pdf_with_layered_rendering()
```
{{< /tab >}}
{{< tab "sample.pdf" >}}
{{< tab-text >}}
`sample.pdf` is the sample file used in this example. Click [here](https://docs.groupdocs.com/viewer/python-net/_sample_files/rendering-basics/render-pdf-documents/sample.pdf) to download it.
{{< /tab-text >}}
{{< /tab >}}
{{< tab "render-pdf-with-layered-rendering-outputs.zip" >}}
```text
render_pdf_with_layered_rendering/pdf_with_layered_rendering_1.html (849 KB)
render_pdf_with_layered_rendering/pdf_with_layered_rendering_2.html (85 KB)
```
[Download full output](https://docs.groupdocs.com/viewer/python-net/_output_files/rendering-basics/render-pdf-documents/render_pdf_with_layered_rendering/render-pdf-with-layered-rendering-outputs.zip)
{{< /tab >}}
{{< /tabs >}}
## Render PDF files as images
### Convert PDF files to PNG
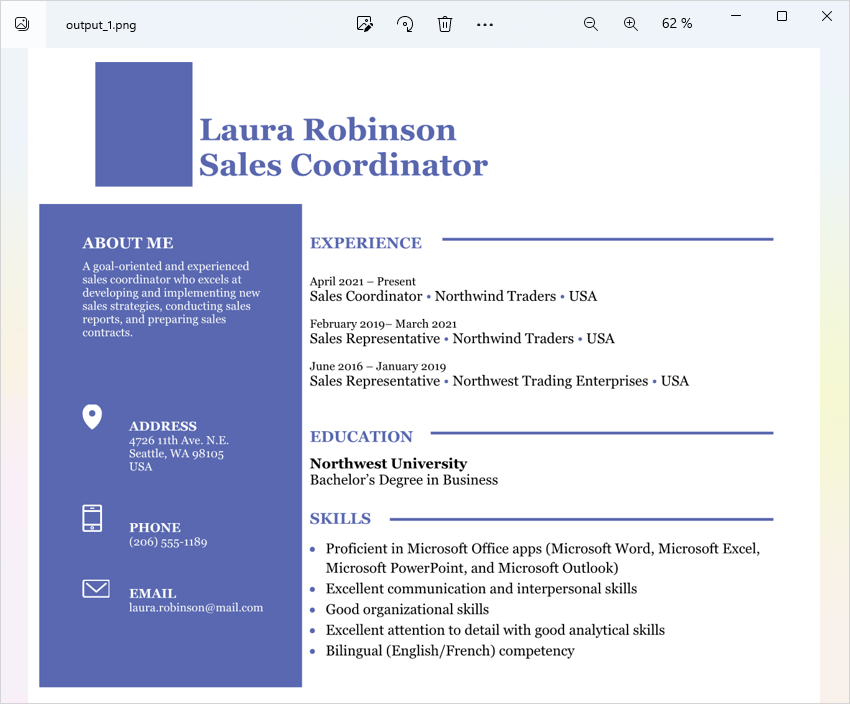
Create a [PngViewOptions](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/pngviewoptions/) class instance and pass it to the [Viewer.view](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer/viewer/#methods) method to convert a PDF file to PNG. Use the [PngViewOptions.height](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/pngviewoptions/#properties) and [PngViewOptions.width](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/pngviewoptions/#properties) methods to specify the output image size in pixels.
{{< tabs "example7">}}
{{< tab "Python" >}}
```python
from groupdocs.viewer import Viewer
from groupdocs.viewer.options import PngViewOptions
def render_pdf_to_png():
# Load PDF document
with Viewer("sample.pdf") as viewer:
# Create a PNG image for each PDF page.
# {0} is replaced with the current page number in the image name.
viewOptions = PngViewOptions("render_pdf_to_png/pdf_page_{0}.png")
# Set width and height.
viewOptions.width = 950
viewOptions.height = 550
viewer.view(viewOptions)
if __name__ == "__main__":
render_pdf_to_png()
```
{{< /tab >}}
{{< tab "sample.pdf" >}}
{{< tab-text >}}
`sample.pdf` is the sample file used in this example. Click [here](https://docs.groupdocs.com/viewer/python-net/_sample_files/rendering-basics/render-pdf-documents/sample.pdf) to download it.
{{< /tab-text >}}
{{< /tab >}}
{{< tab "render-pdf-to-png-outputs.zip" >}}
```text
render_pdf_to_png/pdf_page_1.png (430 KB)
render_pdf_to_png/pdf_page_2.png (42 KB)
```
[Download full output](https://docs.groupdocs.com/viewer/python-net/_output_files/rendering-basics/render-pdf-documents/render_pdf_to_png/render-pdf-to-png-outputs.zip)
{{< /tab >}}
{{< /tabs >}}
The following image demonstrates the result:
### Convert PDF files to JPEG
Create a [JpgViewOptions](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/jpgviewoptions) class instance and pass it to the [Viewer.view](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer/viewer/#methods) method to convert a PDF file to JPEG. Use the [JpgViewOptions.height](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/jpgviewoptions/#properties) and [JpgViewOptions.width](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/jpgviewoptions/#properties) methods to specify the output image size in pixels.
{{< tabs "example8">}}
{{< tab "Python" >}}
```python
from groupdocs.viewer import Viewer
from groupdocs.viewer.options import JpgViewOptions
def render_pdf_to_jpg():
# Load PDF document
with Viewer("sample.pdf") as viewer:
# Create a JPG image for each PDF page.
# {0} is replaced with the current page number in the image name.
viewOptions = JpgViewOptions("render_pdf_to_jpg/pdf_to_jpg_{0}.jpg")
# Set width and height.
viewOptions.width = 950
viewOptions.height = 550
viewer.view(viewOptions)
if __name__ == "__main__":
render_pdf_to_jpg()
```
{{< /tab >}}
{{< tab "sample.pdf" >}}
{{< tab-text >}}
`sample.pdf` is the sample file used in this example. Click [here](https://docs.groupdocs.com/viewer/python-net/_sample_files/rendering-basics/render-pdf-documents/sample.pdf) to download it.
{{< /tab-text >}}
{{< /tab >}}
{{< tab "render-pdf-to-jpg-outputs.zip" >}}
```text
render_pdf_to_jpg/pdf_to_jpg_1.jpg (112 KB)
render_pdf_to_jpg/pdf_to_jpg_2.jpg (33 KB)
```
[Download full output](https://docs.groupdocs.com/viewer/python-net/_output_files/rendering-basics/render-pdf-documents/render_pdf_to_jpg/render-pdf-to-jpg-outputs.zip)
{{< /tab >}}
{{< /tabs >}}
### Preserve the size of document pages
When you render PDF documents as images, GroupDocs.Viewer calculates the optimal image size to achieve better rendering quality. If you want the generated images to be the same size as pages in the source PDF document, use the [PdfOptions.render_original_page_size](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/pdfoptions/#properties) method of the [PngViewOptions](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/pngviewoptions/#properties) or [JpgViewOptions](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/jpgviewoptions/#properties) class (depending on the output image format).
{{< tabs "example9">}}
{{< tab "Python" >}}
```python
from groupdocs.viewer import Viewer
from groupdocs.viewer.options import PngViewOptions
def render_pdf_preserve_page_size():
# Load PDF document
with Viewer("sample.pdf") as viewer:
# Create a PNG image for each PDF page.
# {0} is replaced with the current page number in the image name.
viewOptions = PngViewOptions("render_pdf_preserve_page_size/pdf_preserve_page_size_{0}.png")
# Preserve the size of document pages.
viewOptions.pdf_options.render_original_page_size = True
viewer.view(viewOptions)
if __name__ == "__main__":
render_pdf_preserve_page_size()
```
{{< /tab >}}
{{< tab "sample.pdf" >}}
{{< tab-text >}}
`sample.pdf` is the sample file used in this example. Click [here](https://docs.groupdocs.com/viewer/python-net/_sample_files/rendering-basics/render-pdf-documents/sample.pdf) to download it.
{{< /tab-text >}}
{{< /tab >}}
{{< tab "render-pdf-preserve-page-size-outputs.zip" >}}
```text
render_pdf_preserve_page_size/pdf_preserve_page_size_1.png (364 KB)
render_pdf_preserve_page_size/pdf_preserve_page_size_2.png (30 KB)
```
[Download full output](https://docs.groupdocs.com/viewer/python-net/_output_files/rendering-basics/render-pdf-documents/render_pdf_preserve_page_size/render-pdf-preserve-page-size-outputs.zip)
{{< /tab >}}
{{< /tabs >}}
### Enable font hinting
To adjust the display of outline fonts when you convert PDF documents to PNG or JPEG, use the [PdfOptions.enable_font_hinting](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/pdfoptions/#properties) method, as shown below:
{{< tabs "example10">}}
{{< tab "Python" >}}
```python
from groupdocs.viewer import Viewer
from groupdocs.viewer.options import PngViewOptions
def render_pdf_with_font_hinting():
# Load PDF document
with Viewer("sample.pdf") as viewer:
# Create a PNG image for each PDF page.
# {0} is replaced with the current page number in the image name.
viewOptions = PngViewOptions("render_pdf_with_font_hinting/pdf_with_font_hinting_{0}.png")
# Enable font hinting
viewOptions.pdf_options.enable_font_hinting = True
viewer.view(viewOptions)
if __name__ == "__main__":
render_pdf_with_font_hinting()
```
{{< /tab >}}
{{< tab "sample.pdf" >}}
{{< tab-text >}}
`sample.pdf` is the sample file used in this example. Click [here](https://docs.groupdocs.com/viewer/python-net/_sample_files/rendering-basics/render-pdf-documents/sample.pdf) to download it.
{{< /tab-text >}}
{{< /tab >}}
{{< tab "render-pdf-with-font-hinting-outputs.zip" >}}
```text
render_pdf_with_font_hinting/pdf_with_font_hinting_1.png (1309 KB)
render_pdf_with_font_hinting/pdf_with_font_hinting_2.png (100 KB)
```
[Download full output](https://docs.groupdocs.com/viewer/python-net/_output_files/rendering-basics/render-pdf-documents/render_pdf_with_font_hinting/render-pdf-with-font-hinting-outputs.zip)
{{< /tab >}}
{{< /tabs >}}
Refer to the following article for more information on font hinting: [Font hinting](https://en.wikipedia.org/wiki/Font_hinting).
## Disable character grouping
When you render PDF files in other formats, GroupDocs.Viewer groups individual characters into words to improve rendering performance. If your document contains hieroglyphic or special symbols, you may need to disable character grouping to generate a more precise layout. To do this, use the [PdfOptions.disable_chars_grouping]((https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/pdfoptions/#properties) method, as shown below:
{{< tabs "example11">}}
{{< tab "Python" >}}
```python
from groupdocs.viewer import Viewer
from groupdocs.viewer.options import PngViewOptions
def render_pdf_disable_char_grouping():
# Load PDF document
with Viewer("sample.pdf") as viewer:
# Create a PNG image for each PDF page.
# {0} is replaced with the current page number in the image name.
viewOptions = PngViewOptions("render_pdf_disable_char_grouping/pdf_disable_char_grouping_{0}.png")
# Disable character grouping.
viewOptions.pdf_options.disable_chars_grouping = True
viewer.view(viewOptions)
if __name__ == "__main__":
render_pdf_disable_char_grouping()
```
{{< /tab >}}
{{< tab "sample.pdf" >}}
{{< tab-text >}}
`sample.pdf` is the sample file used in this example. Click [here](https://docs.groupdocs.com/viewer/python-net/_sample_files/rendering-basics/render-pdf-documents/sample.pdf) to download it.
{{< /tab-text >}}
{{< /tab >}}
{{< tab "render-pdf-disable-char-grouping-outputs.zip" >}}
```text
render_pdf_disable_char_grouping/pdf_disable_char_grouping_1.png (1309 KB)
render_pdf_disable_char_grouping/pdf_disable_char_grouping_2.png (100 KB)
```
[Download full output](https://docs.groupdocs.com/viewer/python-net/_output_files/rendering-basics/render-pdf-documents/render_pdf_disable_char_grouping/render-pdf-disable-char-grouping-outputs.zip)
{{< /tab >}}
{{< /tabs >}}
## Render text comments
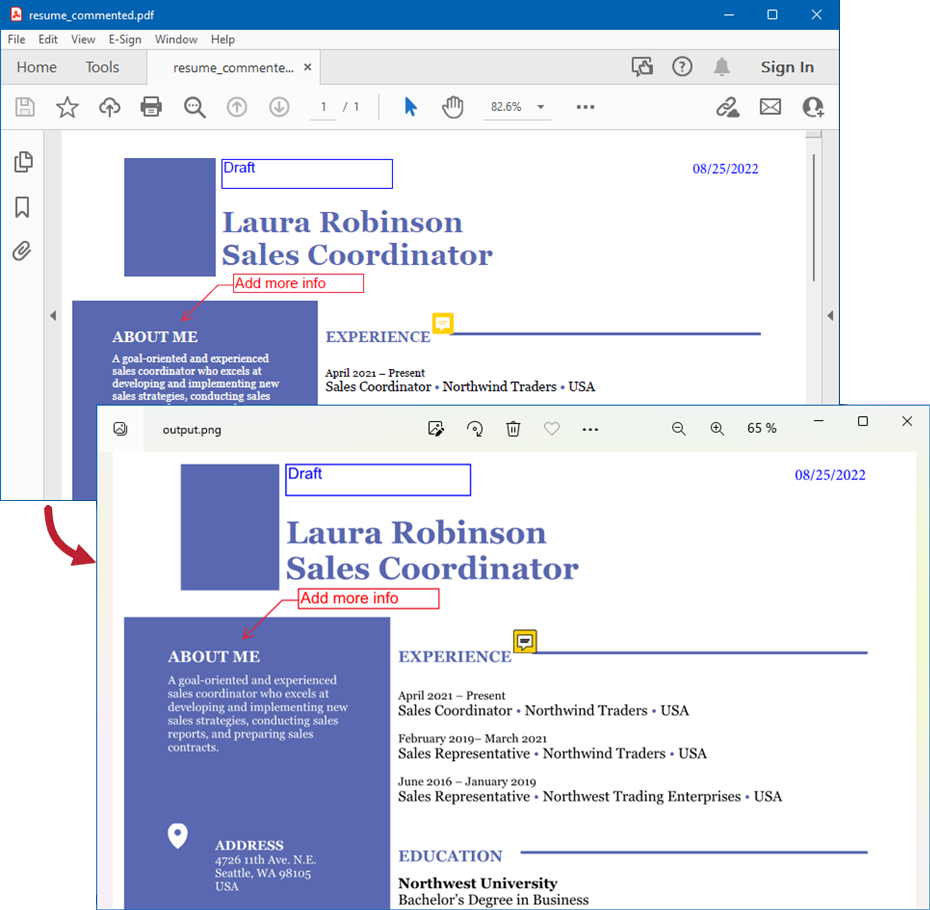
Use the [ViewOptions.render_comments](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/viewoptions/#properties) method for a target view to display textual annotations (such as text comments, sticky notes, text boxes and callouts) in the output HTML, PNG, or JPEG files.
The code example below renders a PDF file with text comments as an image.
{{< tabs "example12">}}
{{< tab "Python" >}}
```python
from groupdocs.viewer import Viewer
from groupdocs.viewer.options import PngViewOptions
def render_pdf_with_comments():
# Load PDF document
with Viewer("sample.pdf") as viewer:
# Create a PNG image for each PDF page.
# {0} is replaced with the current page number in the image name.
viewOptions = PngViewOptions("render_pdf_with_comments/pdf_with_comments_{0}.png")
# Enable rendering comments.
viewOptions.render_comments = True
viewer.view(viewOptions)
if __name__ == "__main__":
render_pdf_with_comments()
```
{{< /tab >}}
{{< tab "sample.pdf" >}}
{{< tab-text >}}
`sample.pdf` is the sample file used in this example. Click [here](https://docs.groupdocs.com/viewer/python-net/_sample_files/rendering-basics/render-pdf-documents/sample.pdf) to download it.
{{< /tab-text >}}
{{< /tab >}}
{{< tab "render-pdf-with-comments-outputs.zip" >}}
```text
render_pdf_with_comments/pdf_with_comments_1.png (1309 KB)
render_pdf_with_comments/pdf_with_comments_2.png (100 KB)
```
[Download full output](https://docs.groupdocs.com/viewer/python-net/_output_files/rendering-basics/render-pdf-documents/render_pdf_with_comments/render-pdf-with-comments-outputs.zip)
{{< /tab >}}
{{< /tabs >}}
The following image illustrates the result:
## Get information about a PDF file
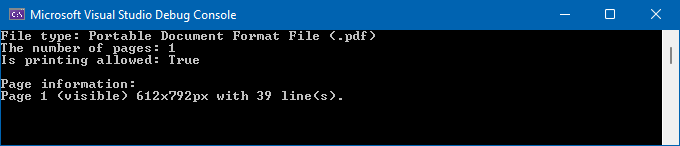
Follow the steps below to obtain information about a PDF file (the number of pages, page size, and printing permissions):
1. Create a [ViewInfoOptions](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/viewinfooptions) instance for a specific view.
2. Call the [Viewer.get_view_info](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer/viewer/#methods) method, pass the `ViewInfoOptions` instance to this method as a parameter, and cast the returned object to the [PdfViewInfo](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.results/pdfviewinfo/) type.
3. Use the `PdfViewInfo` class properties to retrieve document-specific information.
{{< tabs "example13">}}
{{< tab "Python" >}}
```python
from groupdocs.viewer import Viewer
from groupdocs.viewer.options import ViewInfoOptions
def get_pdf_information():
# Load PDF document
with Viewer("sample.pdf") as viewer:
viewInfoOptions = ViewInfoOptions.for_html_view()
view_info = viewer.get_view_info(viewInfoOptions)
# Display information about the PDF document.
print("File type:", view_info.file_type)
print("The number of pages:", len(view_info.pages))
if __name__ == "__main__":
get_pdf_information()
```
{{< /tab >}}
{{< tab "sample.pdf" >}}
{{< tab-text >}}
`sample.pdf` is the sample file used in this example. Click [here](https://docs.groupdocs.com/viewer/python-net/_sample_files/rendering-basics/render-pdf-documents/sample.pdf) to download it.
{{< /tab-text >}}
{{< /tab >}}
{{< tab "get-pdf-information.txt" >}}
```text
File type: Portable Document Format File (.pdf)
The number of pages: 2
```
[Download full output](https://docs.groupdocs.com/viewer/python-net/_output_files/rendering-basics/render-pdf-documents/get_pdf_information/get-pdf-information.txt)
{{< /tab >}}
{{< /tabs >}}
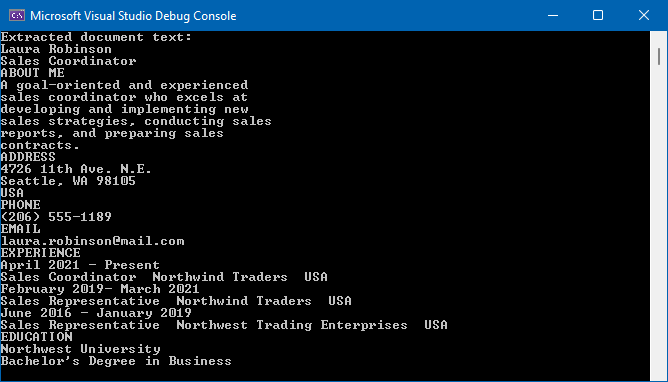
The following image shows a sample console output:
### Extract text from a PDF file
Use the [ViewInfoOptions.extract_text](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.options/viewinfooptions/#properties) method to enable PDF text extraction. Use the [PdfViewInfo.pages](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.results/pdfviewinfo/#properties) methods to obtain the list of all document pages, and use the [Page.lines](https://reference.groupdocs.com/viewer/python-net/groupdocs.viewer.results/page/#properties) method to retrieve text for each line.
{{< tabs "example14">}}
{{< tab "Python" >}}
```python
import sys
from typing import cast
from groupdocs.viewer import Viewer
from groupdocs.viewer.options import ViewInfoOptions
from groupdocs.viewer.results import PdfViewInfo
def extract_pdf_text():
# Load PDF document
with Viewer("sample.pdf") as viewer:
view_info_options = ViewInfoOptions.for_html_view()
view_info_options.extract_text = True
view_info = viewer.get_view_info(view_info_options)
pdf_info = cast(PdfViewInfo, view_info)
# Retrieve text from the PDF file.
sys.stdout.reconfigure(encoding='utf-8')
for page in pdf_info.pages:
print(f"Page: {page.number}")
print("Text lines/words/characters:")
for line in page.lines:
text = str(line)
encoded_line = text.encode('utf-8')
sys.stdout.buffer.write(encoded_line)
# Collect words as array
words = [word.value for word in line.words]
print("\tWords:", words)
# Collect characters for each word as array
for word in line.words:
characters = [char.value for char in word.characters]
print(f"\t\tCharacters for '{word.value}':", characters)
if __name__ == "__main__":
extract_pdf_text()
```
{{< /tab >}}
{{< tab "sample.pdf" >}}
{{< tab-text >}}
`sample.pdf` is the sample file used in this example. Click [here](https://docs.groupdocs.com/viewer/python-net/_sample_files/rendering-basics/render-pdf-documents/sample.pdf) to download it.
{{< /tab-text >}}
{{< /tab >}}
{{< tab "extract-pdf-text.txt" >}}
```text
Page: 1
Text lines/words/characters:
Line 'How to fold origami candy boxes' X=141.14 Y=76.4052 313.12501x22.044px with 6 word(s). Words: ['How', 'to', 'fold', 'origami', 'candy', 'boxes']
Characters for 'How': ['H', 'o', 'w']
Characters for 'to': ['t', 'o']
Characters for 'fold': ['f', 'o', 'l', 'd']
Characters for 'origami': ['o', 'r', 'i', 'g', 'a', 'm', 'i']
Characters for 'candy': ['c', 'a', 'n', 'd', 'y']
Characters for 'boxes': ['b', 'o', 'x', 'e', 's']
Line 'How about folding
[TRUNCATED]
```
[Download full output](https://docs.groupdocs.com/viewer/python-net/_output_files/rendering-basics/render-pdf-documents/extract_pdf_text/extract-pdf-text.txt)
{{< /tab >}}
{{< /tabs >}}